Home › AI & Automation › Mistral Large 4
AI & Automation
Mistral Large 4 Is Here: 1T Parameters, 1M Context, Pricing, Benchmarks and Open Weights
Mistral’s new “Le Chonk” flagship enters public preview with 1.05T total parameters, 49B active parameters and a 1M context window. Here’s what its pricing, benchmark claims, API access and October open-weight release mean in practice.
Published October 6, 2026 · Digital Pulse Brief Editorial Desk · Facts checked against Mistral and Reuters before publication
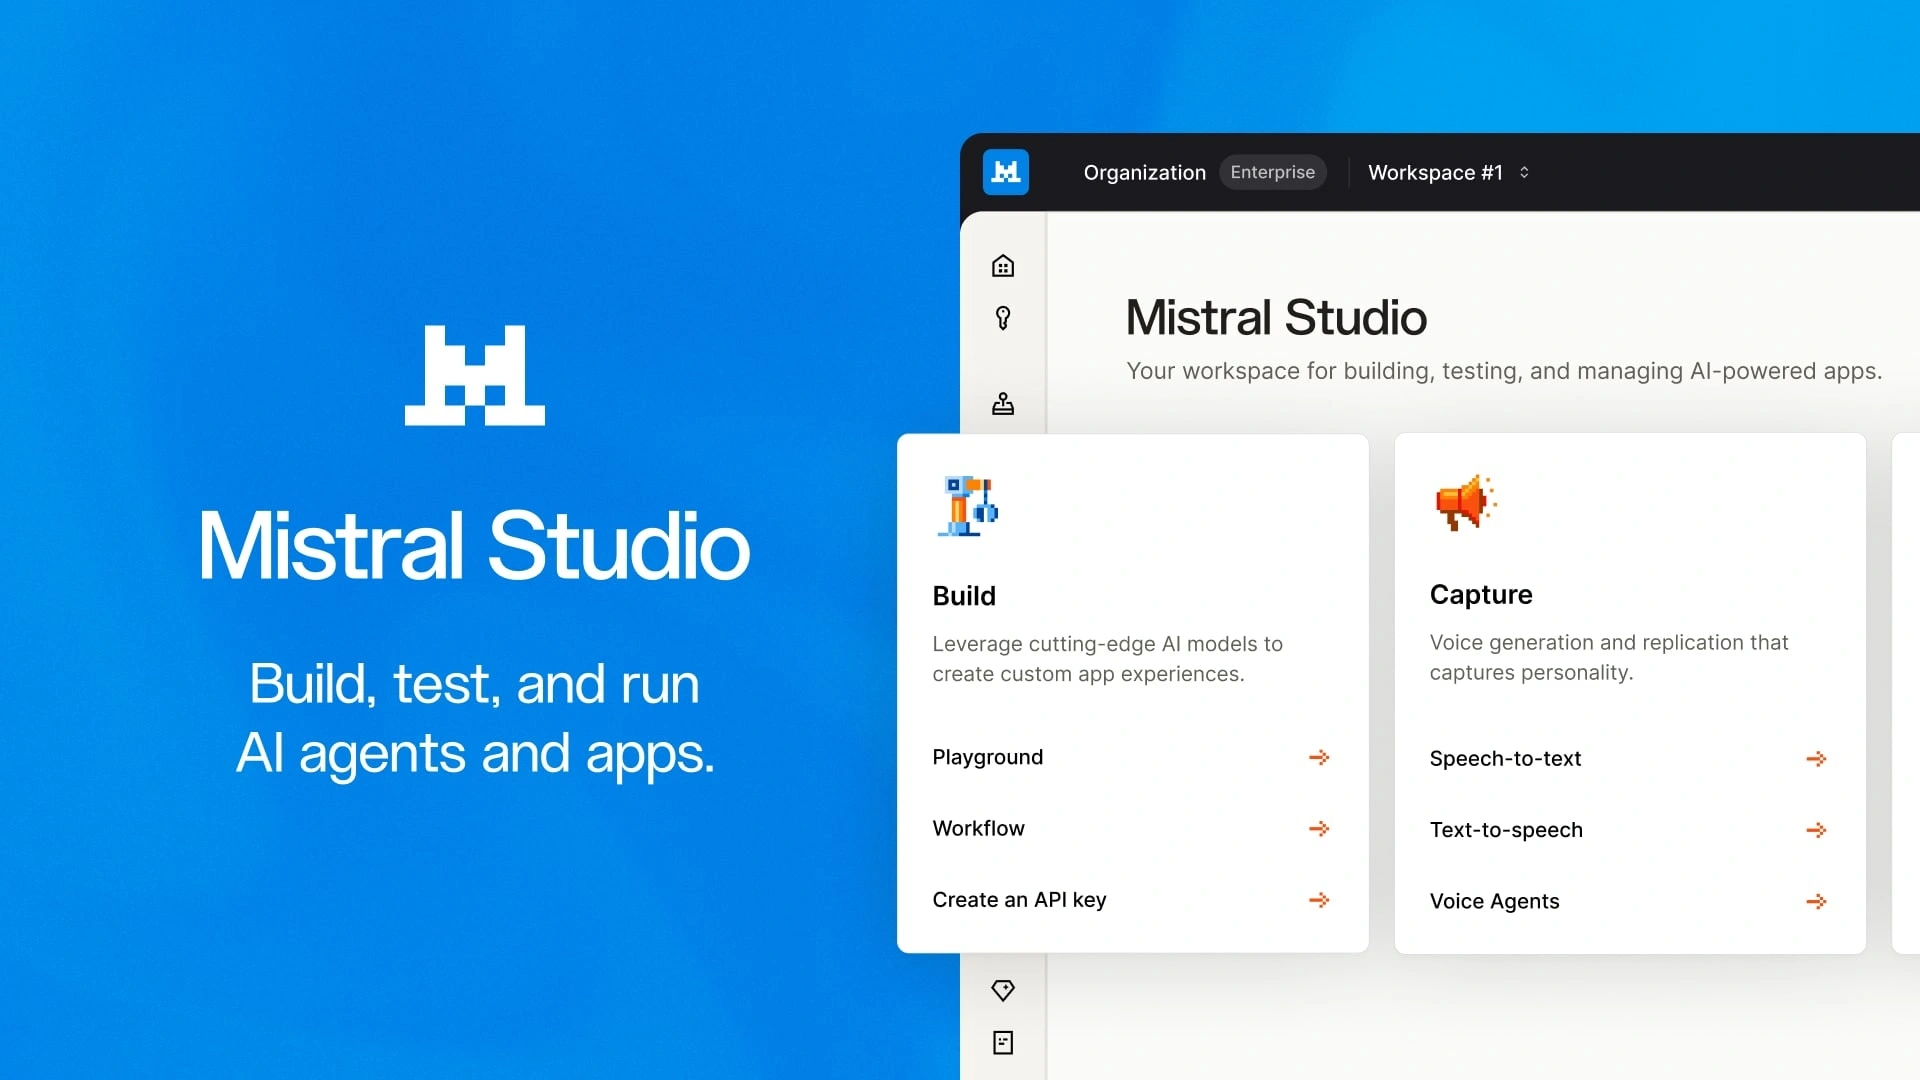
Image credit: Mistral. Official Mistral Studio product artwork from the company’s published brand assets; Studio is where the Large 4 public preview can be tested.
Mistral Large 4 is now in public preview. Mistral introduced the model on October 6, 2026 as its largest system yet: a multimodal Mixture-of-Experts model with 1.05 trillion total parameters, 49 billion active parameters, a 1.6 billion-parameter vision encoder and a 1 million-token context window. The preview is available through Mistral Studio and the API today, while the downloadable weights are scheduled for later in October.
Quick answer
What is Mistral Large 4? It is Mistral’s new flagship open-weight multimodal model, also nicknamed “Le Chonk.”
Can you use it now? Yes, the hosted public-preview API is available now. The open weights are not yet generally downloadable.
When do the weights arrive? Mistral says by the end of October. Reuters reports October 27 as the planned public release date.
Mistral Large 4 specs at a glance
| Item | Mistral Large 4 | Why it matters |
|---|---|---|
| Release status | Public Preview, v26.10 | Hosted API access is live, but the model is still being refined |
| Architecture | Granular Mixture-of-Experts | Only a subset of the full parameter set is active for a token |
| Total parameters | 1.05T | Shows the scale of the full model, not the compute used for every token |
| Active parameters | 49B | More useful than the headline 1T figure for understanding MoE inference behavior |
| Vision encoder | 1.6B parameters | Supports native multimodal image/document understanding |
| Context window | 1M tokens | Targets long documents, repositories and agentic workflows |
| Languages | 160+ in Mistral’s training description | Includes every official language of the European Union, according to Mistral |
| Model ID | mistral-large-4 | Used for supported API requests |
The headline “1 trillion parameters” needs context. Mistral Large 4 is not a dense one-trillion-parameter model executing every parameter for every token. It is a Mixture-of-Experts system with 49 billion active parameters. That distinction is important when comparing architecture, serving cost and practical deployment.
What launched on October 6 — and what did not
Mistral opened a public preview of Large 4 through its hosted platform. The company says users can try the model in Mistral Studio now, and its documentation lists support for chat completions, structured outputs, function calling, document Q&A, batching, Agents & Conversations and built-in tools.
What has not happened yet is the full open-weight release. Mistral’s own launch post says the weights will arrive by the end of the month. Reuters reports that Mistral plans to make the model publicly available on October 27, 2026. Until the weights actually ship, claims about exact self-hosting memory requirements, quantized variants or real-world local throughput should be treated as premature.
Bottom line: Large 4 is usable today as a hosted preview. It is not yet the same thing as having the downloadable model weights in hand.
Mistral Large 4 pricing: the docs currently show two price levels
There is an important detail in Mistral’s own pages. The launch article lists $1.36 per million input tokens and $4.18 per million output tokens. Mistral’s model documentation currently displays those amounts as higher, struck-through figures and shows lower values of $0.68 input, $0.07 cached input and $2.09 output per million tokens.
| Token type | Model page currently displays | Higher/list figure shown |
|---|---|---|
| Input | $0.68 / 1M tokens | $1.36 / 1M |
| Cached input | $0.07 / 1M tokens | $0.14 / 1M |
| Output | $2.09 / 1M tokens | $4.18 / 1M |
Because the model is in public preview and the presentation differs between the launch story and model page, buyers should check the live Mistral pricing shown in Studio before budgeting a production workload. Digital Pulse Brief is reporting the values visible on Mistral’s pages on October 6 rather than assuming the lower rate is permanent.
Image credit: Mistral. Official gradient logo lockup used under Mistral’s published brand guidelines.
How strong are the Mistral Large 4 benchmarks?
Mistral is making aggressive performance claims, but the safest way to read them is benchmark by benchmark. Some numbers come from third-party evaluation suites cited by Mistral; others are company-run or company-presented comparisons. None of these results should be confused with a Digital Pulse Brief hands-on test.
| Area | Reported result | How to interpret it |
|---|---|---|
| Agentic coding | 61.7% DeepSWE v1.1; 59.4% SWE-Atlas-QnA; 28.3% Terminal-Bench 4; Coding Agent Index 49.8% | Mistral cites Artificial Analysis for several coding-index numbers |
| Blind coding quality | 3.74/5 in a Surge AI evaluation | Ahead of Kimi K3 and two GLM variants in Mistral’s reported table, behind Claude Opus 5 at 4.22 |
| Business agents | 59.9% on AutomationBench | Tests 657 workflows across business applications |
| Cybersecurity | 82% on a vulnerability reproduce-and-patch test; 93% of Cybench challenges | Potentially important for defenders, but cyber capability also raises safety and governance questions |
| Visual grounding | 42% on Dense 200 versus 41% for GPT-6 Astra in Mistral’s comparison | A narrow benchmark result, not proof of superiority across all multimodal tasks |
| Prompt-injection resistance | 93.3% attack resistance on Lakera’s B3 benchmark | One useful security signal, not a guarantee that deployed agents are safe |
The most interesting result is not necessarily the largest number. Large 4 is being positioned as a model that combines coding, tool use, multimodal input and security work rather than optimizing for a single leaderboard. That is the same broad direction visible across the frontier-model market: users increasingly care about whether a model can operate across repositories, documents, images and tools in one workflow.
Why Mistral is emphasizing cybersecurity
Mistral says Large 4 ranks among the top five models on the Artificial Analysis Cyber Index and describes it as its strongest model for security work. The company is also doing something unusual before releasing the weights: it says cybersecurity leaders, vetted partners and state authorities will red-team the same model with reduced moderation and expanded cyber capabilities.
This matters because capable security models sit on a difficult line. Defensive teams may need a model to reproduce a vulnerability, analyze malware or test exploitability before they can patch a system. At the same time, those capabilities can be misused. Mistral argues that open weights and self-deployment can give legitimate defenders more control over model policy and availability, but organizations would still need their own access controls, logging, isolation and human review.
Security note: benchmark performance does not remove operational risk. An enterprise deployment still needs normal security engineering around the model, especially when agents can call tools or touch production systems.
Why the open-weight release matters more than the nickname
“Le Chonk” is memorable, but the strategically important part of the launch is Mistral’s commitment to release the weights. If that happens on the announced schedule, organizations will be able to evaluate a frontier-scale Western model outside a vendor-only API environment and potentially run it on infrastructure they control.
Open weights do not automatically mean cheap or easy self-hosting. Large 4 has 1.05 trillion total parameters, and Mistral has not yet published all the architecture, post-training and deployment details it says will accompany the weights. Until those files and technical notes are released, concrete claims about GPU counts for inference, practical quantization quality or workstation deployment would be speculation.
The architecture does, however, help explain why the model is not equivalent to running a dense one-trillion-parameter network for each generated token. Its 49 billion active parameters are a key part of the efficiency story. The final deployment story will depend on expert routing, memory layout, weight precision, serving software, batching and the hardware used.
Trained in Europe on 3,800 Grace Blackwell GPUs
Mistral says Large 4 was trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in its own European datacenters, and that the public preview is served on the same infrastructure. The company also says a substantial share of the training data was multilingual across more than 160 languages.
The infrastructure detail is central to Mistral’s sovereign-AI pitch. It is not merely selling model access; it is arguing that customers should be able to choose where inference happens, how models are deployed and, eventually, whether they run the weights themselves. Mistral’s regional-inference documentation separately offers EU and US endpoints for organizations that need to control the geography of inference processing, with a 10% regional upcharge over standard list pricing.
Mistral also says the reinforcement-learning run behind the preview is still active. At its current scale of roughly 3,000 GPUs, the company says a run generates about 33 billion tokens per day, leaving around 16 billion trainable completion tokens after filtering and masking. That makes the “preview” label meaningful: the model may still change before the weight release.
What Large 4 changes in the open-model race
The broader story is competition. For much of the open-weight frontier, Chinese model developers have set the pace on price-performance and downloadable capabilities. Mistral is presenting Large 4 as evidence that a European developer can compete at that level while combining open weights with its own cloud, regional infrastructure and enterprise customization stack.
Reuters reported that Mistral views the model as competitive with Chinese rivals in several areas, especially cybersecurity. That claim will become easier to assess once the weights are public and independent labs can run the same checkpoints under reproducible conditions.
For developers, the competitive pressure is useful regardless of which vendor wins a leaderboard. More strong open-weight options can reduce dependence on one API provider, create more deployment choices and push pricing down. For enterprises, the harder question is not simply “which model scores highest?” but which model meets requirements for accuracy, latency, data location, governance, integration and total cost.
Image credit: Mistral. Official Mistral Compute product artwork, relevant to the company’s European training and inference infrastructure.
How to try Mistral Large 4 now
The public preview is available through Mistral Studio and the Mistral API. Mistral’s documentation identifies the model as mistral-large-4 and lists support for structured outputs, function calling, document Q&A, chat completions, batching, agents and built-in tools.
Practical developer path
- Create or use a Mistral Studio account and verify the live pricing for your region/account.
- Test the model in the Studio interface before wiring it into production.
- For API use, select
mistral-large-4and start with a bounded evaluation set. - Measure your own quality, latency, token use and tool-calling reliability instead of relying only on launch benchmarks.
- If open-weight deployment is your goal, wait for the October weight release and the accompanying architecture/deployment details before sizing hardware.
For production systems, a preview label should change how you evaluate risk. Pin model versions where the platform allows it, test important prompts against regressions, and avoid assuming that preview behavior or pricing will remain unchanged.
Who should care about Mistral Large 4?
Developers comparing frontier APIs
Large 4 adds another high-end multimodal option with long context, agent features and a competitive preview price presentation.
Teams that need open weights
The October weight release could matter for private-cloud, on-premise and customized deployments—but the files need to ship before those plans can be validated.
Security and infrastructure teams
Mistral is explicitly targeting cyber defense and sovereign deployment, making independent safety and operational testing especially important.
Enterprises with data-location requirements
Mistral’s EU/US regional-inference options and European infrastructure make the deployment story part of the product decision, not just the benchmark score.
What we still do not know
- Independent post-release performance: many headline benchmark results are presented by Mistral, even when underlying evaluators are third parties.
- Final open-weight deployment requirements: the weights and full technical release are not public yet.
- Whether preview pricing will persist: Mistral’s model page currently shows lower figures next to higher struck-through rates, while the launch article lists the higher input/output values.
- How the final checkpoint will differ from today’s preview: Mistral says reinforcement learning is still underway.
- Real workload fit: benchmark scores cannot substitute for testing on an organization’s own documents, repositories, tools and security constraints.
Digital Pulse Brief has not performed a hands-on benchmark of Mistral Large 4. This article is based on Mistral’s official launch material and documentation, cross-checked against Reuters reporting and the company’s published platform information.
Mistral Large 4 FAQ
Is Mistral Large 4 available now?
Yes, as a hosted public preview through Mistral Studio and the API. The downloadable weights are scheduled for later in October 2026.
When will Mistral Large 4 open weights be released?
Mistral says by the end of October. Reuters reports a planned October 27 release. Until the weights are actually published, treat that date as a planned schedule rather than a completed release.
How many parameters does Mistral Large 4 have?
Mistral documents 1.05 trillion total parameters and 49 billion active parameters, plus a 1.6 billion-parameter vision encoder.
What is the context window?
The official model documentation lists a 1 million-token context window.
Can Mistral Large 4 run on a local PC?
It is too early to give a responsible consumer-PC requirement. The open weights, exact packaging and practical quantization details have not yet been released. A 1.05T-total-parameter MoE model should not be treated as a typical desktop model simply because only 49B parameters are active per token.
Is Mistral Large 4 better than Claude, GPT or Chinese open models?
There is no single defensible yes-or-no answer. Mistral reports wins on selected coding, cyber, visual and enterprise evaluations, while its own blind coding table still places Claude Opus 5 above Large 4. Independent testing after the weight release will give a clearer picture across workloads.
Sources and verification
- Mistral — Introducing Mistral Large 4 (October 6, 2026)
- Mistral Docs — Mistral Large 4 model page
- Mistral Docs — Regional inference
- Reuters — Mistral launches Large 4 (October 6, 2026)
- Mistral — Official brand assets and guidelines
Continue reading
Compare the wider frontier-model landscape
Read Digital Pulse Brief’s recent explainers on Google’s Gemini 4 Argon and Anthropic’s Claude Sonnet 5.5 vs Opus 5.5.
Gemini 4 Argon explained →
Claude Sonnet 5.5 vs Opus 5.5 →
Explore AI & Automation →
Last checked: October 6, 2026. Pricing, preview behavior and the open-weight release schedule may change. We will update this article when Mistral publishes the final weights or material technical details.
DIGITAL PULSE BRIEF NEWSLETTER
Get clear AI, technology and business insights in your inbox
Breaking developments, practical explainers, reviews and useful tech intelligence — without the noise.
WHAT TO READ NEXT
Amazon Bedrock Managed Agents Powered by OpenAI: Pricing, Regions, IAM, AgentCore and Limits  OpenAI textGrain Watermarking Explained: What Changes for ChatGPT, Codex and API Users
 Claude Sonnet 5.5 vs Opus 5.5: Price, Benchmarks, Coding and Which Model to Use
MORE FROM DIGITAL PULSE BRIEF